How to Build a Recommender System: Collaborative vs Content-Based

18 minutes to read
Get free consultation

How to Build a Recommender System for E-Commerce

Modern retail relies on personalization to drive sustainable revenue. Shoppers demand hyper-relevant experiences instantly. Engaging these shoppers requires displaying relevant products, as unrelated items quickly drive them away. Personalization acts as an essential core survival tactic for modern retailers rather than a luxury feature. Modern consumers respond best to intuitive guidance, making generic product grids less effective. You must guide users intuitively.

Tailored product suggestions capture the sales opportunities that generic ones often miss. E-commerce product managers must deliver relevant items to shoppers constantly. Equipping retail engineering leads with strong recommender architectures relieves their massive technical burden. You need to know how to build a recommender system. It must act as a well-oiled data machine. We view data as your most valuable untapped asset. We partner with clients to unlock this data potential securely.

The right pipeline actively drives your average order value (AOV). It also increases overall conversions seamlessly. Recommendation engines analyze user behavior to predict future purchases. A robust system handles massive data volumes effortlessly. It transforms raw clicks into direct revenue streams. We work with you to streamline this entire process. We empower your team to own the architecture completely.

An effective pipeline acts like a personalized digital concierge. It guides customers toward higher-value purchases naturally. We help you build these intelligent data highways. Our clients often see 40% faster insights post-implementation. Building custom assets that grow your business replaces the need to rent generic SaaS algorithms. The goal is clear: your growth. You need a system that understands subtle shopper intent. The engine must react to trends in real time. We make this technical journey accessible and highly profitable.

The Recommender System Pipeline: Beyond the Algorithm

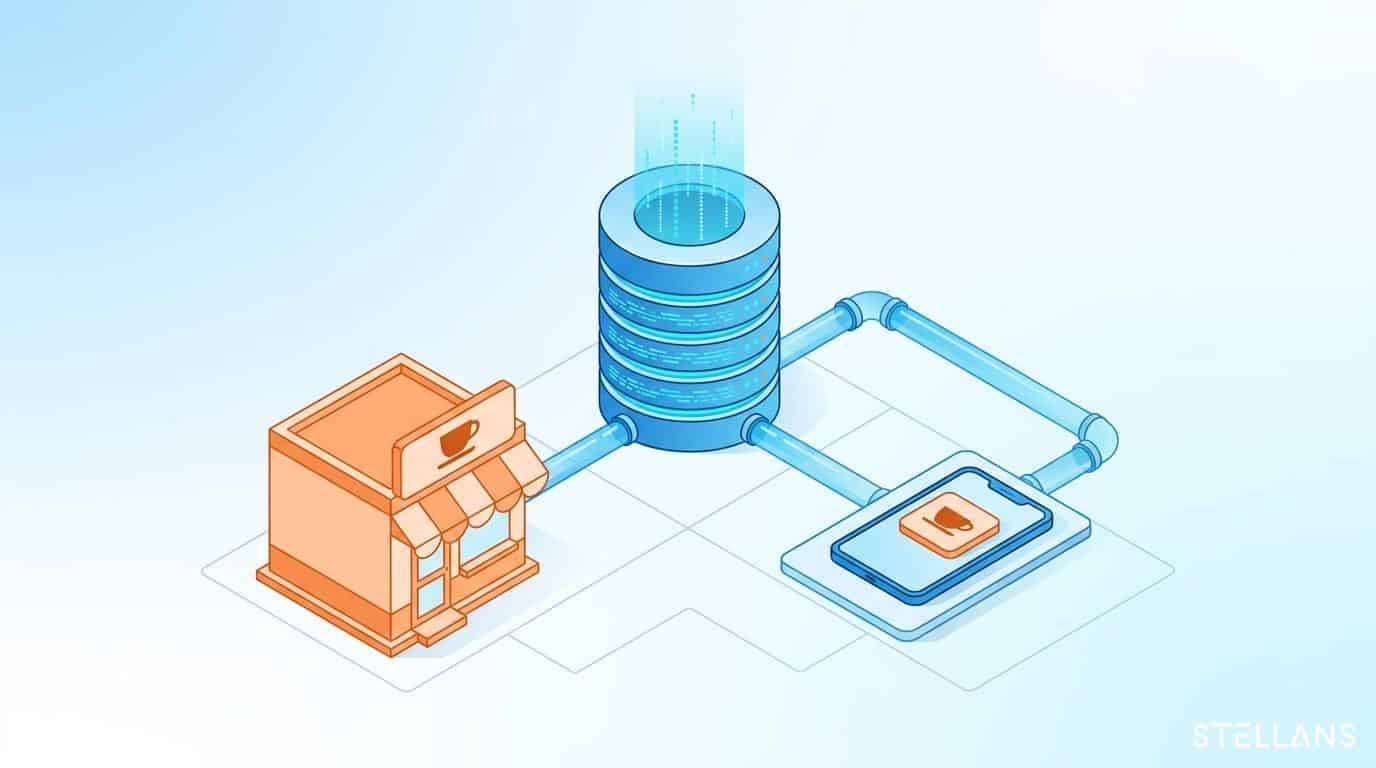
Building a resilient and successful architecture requires a comprehensive end-to-end pipeline, rather than narrowly focusing on the core algorithm. We view the data pipeline as a highway. The algorithm is just the engine inside the car. You need solid roads to reach your destination. The full recommendation pipeline contains six distinct stages.

The Events stage forms the absolute bedrock of your system. It captures clicks, page views, and cart additions constantly. We ensure this data streams into your warehouse flawlessly. Building a successful model relies on pristine and real-time event data. Every single interaction holds predictive value.

The Features stage transforms raw events into intelligent signals. We create rich user profiles based on historical actions. We also parse product metadata meticulously. These features feed directly into the machine learning models. High-quality features ensure your model understands every click perfectly, keeping your pipeline clean and accurate.

Feature engineering dictates the true intelligence of your system. Transforming raw clicks into meaningful behavioral profiles is essential before feeding them into an algorithm. We categorize features into three distinct buckets. First, we have user features. These include demographic data and historical purchase frequencies. Second, we have item features. These cover product categories, price points, and seasonal tags. Third, we have context features. These track the device type, time of day, and current weather. A robust pipeline updates these features continuously. If a user buys a premium watch, their specific price affinity feature updates instantly. We architect these feature stores to serve data with ultra-low latency. High-quality features ensure your model understands the context behind every click.

Candidate Generation must operate with extreme efficiency. A catalog might contain millions of distinct items. Candidate generation uses lightweight algorithms to filter this massive pool efficiently, since scoring every single item for every user requires too much processing time. It selects a few hundred highly probable items quickly.

The Ranking stage applies heavy computational power. It uses deep learning or matrix factorization to score candidates. This stage assigns a precise relevance probability to each item. The highest scores represent the most likely purchases.

The Business Rules engine acts as your commercial safeguard. Algorithms focus strictly on mathematical relevance probabilities. Applying human-defined logic bridges the gap that raw math leaves open. Safeguarding your profitability requires rule engines that intercept anomalies like recommending negative-margin televisions. Rule engines also maintain contextual relevance by preventing suggestions like winter coats during a summer heatwave. We build rule engines to handle these scenarios perfectly. You can inject hard filters to remove out-of-stock items instantly. You can apply soft multipliers to boost house brands. You can cap the number of items shown from a single vendor. This level of control guarantees excellent user experiences. It ensures the machine learning aligns perfectly with your merchandising strategy. We design user-friendly interfaces for these rules. Your marketing team can adjust parameters without writing any code.

Finally, the Serving stage requires robust infrastructure. It must deliver the final list to the frontend in milliseconds. Fast APIs preserve the user experience, while slow deliveries disrupt it completely. We engineer serving layers that withstand massive traffic spikes. A highly optimized pipeline processes data instantly. It reacts immediately when a customer adds an item. This speed directly influences your cart addition rates.

We help retail teams construct this entire foundation. A solid pipeline guarantees reliable and scalable personalization. You need infrastructure that handles traffic spikes gracefully. We build these robust systems for you. Check out our scalable data infrastructure solutions to learn more. A robust pipeline eliminates costly downtime during peak seasons. It ensures your machine learning models always have fresh data. The outcome is simple: higher engagement and increased revenue.
Evaluating Core Approaches to Recommendations

Selecting the right algorithm is a critical business decision. The algorithm determines how your system understands shopper behavior. E-commerce platforms typically rely on three foundational approaches. We help you evaluate these options against your revenue goals. You must understand the strengths and weaknesses of each model.

Here is a comparison of the primary methodologies:

Feature Content-Based Filtering Collaborative Filtering Matrix Factorization
Core Mechanism Matches item attributes to user profiles. Matches users based on similar behavior. Uncovers latent features from interactions.
Key Strengths Requires no other user data. Discovers unexpected cross-category items. Handles large, sparse datasets exceptionally well.
Main Weaknesses Tends to create a narrow filter bubble. Requires existing interaction data to score new items. Requires complex tuning to interpret practically.
Cold-Start Behavior Excels during new product launches. Requires prior data for both users and items to function. Depends entirely on initial interaction data to begin scoring.
Best E-Commerce Uses Niche categories and newly added catalog items. Popular items and dense user traffic zones. Complex catalogs requiring deep hidden patterns.

Collaborative Filtering

Collaborative models map the collective intelligence of your audience. If User A and User B buy similar pants, they are mathematically linked. When User A buys a new shirt, User B sees it. This method creates highly engaging discovery experiences. It mimics the feeling of shopping with a knowledgeable friend. It drives impulse buys by showing popular trending items.

Maintaining variety requires careful tuning to prevent popular items from dominating the carousels constantly. Niche products need specific adjustments to gain algorithmic traction. Functioning effectively also requires dense interaction data.

Content-Based Filtering

Content-based models focus strictly on the catalog items themselves. These models bypass the chaotic behavior of the broader crowd by focusing precisely on catalog attributes. We map the specific attributes of every single product. If a customer buys a red cotton t-shirt, the system notes this. It then recommends other red cotton items instantly.

This approach guarantees thematic consistency for the shopper. It excels in highly specific niche retail markets. It works perfectly for brand new inventory. Generating recommendations relies purely on item attributes rather than historical interactions from other shoppers. While it guarantees thematic consistency, it usually focuses on similar items rather than surprising the user with novel categories. The system prioritizes exact matches over complementary suggestions like a belt for a t-shirt.

Where Matrix Factorization Fits

Matrix factorization bridges the gap between raw data and hidden intent. Imagine a massive grid of users and products. Most of this grid is completely empty. Users only interact with a tiny fraction of your catalog. Matrix factorization compresses this empty grid mathematically. It reveals latent dimensions like style preference or price sensitivity.

We use these latent dimensions to predict missing interactions. This model calculates the probability of a user liking an unseen item. It scales beautifully for massive enterprise datasets. We often implement this to find subtle shopping patterns.

Capturing intent usually involves tracking implicit signals like clicks and purchases, since direct product ratings occur less frequently. We calculate implicit feedback accurately to power these models. Here is the mathematical formula for weighted implicit-feedback interactions:

c_{ui} = 1 + \alpha r_{ui}

In this formula, $c_{ui}$ represents the confidence level. The $\alpha$ parameter scales the interaction importance. The $r_{ui}$ variable represents the raw interaction count. This simple equation transforms basic clicks into powerful intent signals.

Resolving the Cold Start Problem Machine Learning Challenge

Historical data drives algorithmic success, and providing this data prevents the cold start problem machine learning challenge. Capturing early intent protects average order value for new traffic segments. High-value visitors stay when they see relevant products. Mitigating the cold start ensures new product launches succeed seamlessly. Equipping your system with smart fallbacks allows it to recommend new items even before they gather their first clicks. We work with you to navigate these blind spots. You need clear strategies to handle fresh users and items. Solving this challenge directly increases your bottom line.

Personalized landing pages capture expensive traffic efficiently. The user cold start problem represents a massive financial leak. Identifying new visitor intent requires intelligent fallbacks, since the model initially lacks historical purchases or past clicks. You must implement intelligent strategies to capture their interest immediately.

Step-by-Step Mitigation for User Cold Start

Algorithms require quick intent deduction to salvage sessions when new visitors arrive without historical context. You must deduce intent quickly to provide a great experience. We use a progressive six-step mitigation path for this issue.

  1. Context without identity: Capture session data immediately. We analyze the browser type and the referral URL. We check the time of day and the geographic IP location. These subtle clues dictate the first product carousel.
  2. Content-based fallback: Rely on the current page context. If a user views shoes, show similar shoe styles instantly. We extract product metadata to find instant matches.
  3. Segmented popularity: Serve localized trending items to increase relevance rather than showing generic bestsellers. A bestseller in New York might fail in Miami.
  4. Explicit preferences: Ask the user for their preferences during onboarding. We design frictionless onboarding quizzes. We ask them to select three favorite brands quickly.
  5. Collaborative transition: Wait for the user to click 3 to 5 items. Once the user interacts, the system switches gears. It blends their real-time behavior with global patterns.
  6. Incremental testing: A/B test these fallback strategies continuously. We run continuous experiments on these fallback strategies. We rely on data to maximize initial conversions.

These steps ensure new users always see relevant suggestions. You capture their interest before they abandon the site.

Step-by-Step Mitigation for Product Cold Start

Retailers refresh their seasonal catalogs constantly. A new clothing line launches with zero historical interaction data. Standard collaborative filtering algorithms require proven click histories to recommend products effectively. This reliance creates a vicious cycle for new inventory. Fresh items need initial impressions to generate clicks, and they need those clicks to gain algorithmic visibility. We break this cycle with proactive engineering. We implement a seven-step mitigation path for new catalog items.

  1. Metadata ingestion: Ensure every new product has rich metadata attached. Tags, descriptions, and categories are absolutely vital. We mandate complete tags for every new SKU.
  2. Content representations: Convert text descriptions into mathematical vectors. We use natural language processing to understand product similarities.
  3. Controlled placements: Force new items into specific recommendation carousels. Dedicate 15% of slots to newly launched inventory. This guarantees baseline impressions.
  4. Exploration via Bandits: Use Multi-Armed Bandit algorithms to test new items. The algorithm tests new items dynamically. It measures user reactions in real time.
  5. Transfer information: Borrow interaction history from older products. Apply a defunct product’s score to its direct replacement. A V2 product inherits the V1 interaction history.
  6. Blend scores: Combine content-based scores with initial collaborative scores. Fade out the content score as interaction data grows. The collaborative score takes over naturally.
  7. Monitor fairness: Track the exposure rates of new vendors. Balancing catalog exposure ensures your algorithm represents both premium brands and affordable options fairly. We build dashboards to track new item visibility.

This framework guarantees new products receive immediate visibility. It prevents your freshest inventory from gathering digital dust. We empower your team to automate this entire lifecycle.

Designing Hybrid Recommendation Engine Algorithms

Combining multiple algorithms overcomes the rigid limitations of relying on just one. Hybrid systems handle modern retail complexities beautifully. These dynamic engines adapt perfectly when user behavior shifts abruptly. Your data maturity changes as your business scales rapidly. We recommend building hybrid recommendation engine algorithms. These engines combine multiple signals dynamically for optimal results. A hybrid approach provides the best of all worlds. It leverages content data and collaborative patterns simultaneously.

We design systems that adapt to user behavior instantly. The architecture routes queries based on user history depth. If a user is new, it weights content signals heavily. If a user is active, it prioritizes collaborative patterns. This dynamic routing maximizes relevance for every single visitor. We weight these signals based on real-time data confidence. We build these systems using scalable cloud architecture.

Session-based recommendations represent a powerful hybrid feature. These models analyze the exact sequence of current clicks alongside long-term historical profiles. Real-time personalization reacts to sudden shifts in shopper intent. A user might shop for themselves on Tuesday. They might shop for a gift on Thursday. Adapting to current clicks ensures relevance during varied intent periods, such as a gift-shopping session.

The hybrid engine detects this behavioral shift instantly. It discards the historical profile temporarily. It relies solely on the current sequence of clicks. If a user switches from electronics to clothing, the system adapts. The pipeline updates the ranked candidates within milliseconds. This adaptability drives incredible conversion lifts.

We also utilize advanced embedding techniques for hybrid engines. Embeddings map both users and products into a shared space. This mathematical space reveals complex similarities between diverse items. You can combine text embeddings with behavioral embeddings seamlessly. This fusion creates highly accurate, personalized shopping experiences.

Our focus remains on practical business applications. We focus purely on building custom recommendation engines that generate tangible profit. We design custom recommendation engines that deliver exceptional results. We ensure your hybrid system scales efficiently without bloating costs.

Maximizing Shopping Cart Size Metrics and Conversion

Business results validate technical models. We treat metrics as the ultimate source of truth. Tangible commercial goals drive real value. We align every pipeline stage with tangible commercial goals. Your primary objective involves maximizing shopping cart size metrics. You must track how algorithmic changes impact real customer behavior. We help you establish rigorous measurement frameworks for success.

Click-Through Rate (CTR) and Cart Addition Rate (CAR)

Click-Through Rate (CTR) measures initial user interest effectively. It tracks how often shoppers click a suggested item. CTR remains a staple metric in retail analytics. It helps you measure the immediate visual appeal of a recommendation. If CTR drops suddenly, you likely have a UI problem. The carousel might be placed too low on the page.

Evaluating CTR alongside other metrics provides clearer insights, as clicks alone often reflect curiosity rather than intent. Actual product purchases require deeper intent than high clicks guarantee. A user might click an interesting item merely out of curiosity. Revenue tracking requires more robust proxies than CTR alone. Users click on novelty items frequently without any intent to purchase.

Cart Addition Rate (CAR) provides a much stronger signal. CAR measures how often a clicked recommendation enters the cart. This metric proves the suggestion matched the user’s actual intent. CAR separates casual browsing from serious shopping. It filters out the noise of idle curiosity. We instrument your analytics to track this journey meticulously.

We measure the time delay between the click and the cart addition. A rapid cart addition indicates a highly confident prediction. A delayed addition suggests the user needed to read multiple reviews first. We feed this nuanced timing data back into the ranking algorithm. The system learns to prioritize items that drive immediate action. We optimize your pipelines to maximize CAR specifically. A high CAR directly indicates an increase in user purchase readiness. You must prioritize models that drive cart additions over mere clicks.

Direct Attribution Sales and Incremental Revenue

Direct attribution sales measure revenue generated straight from recommendations. If a user clicks a suggestion and buys it, that counts. Direct attribution sales provide a clear baseline for success. We tag every purchase tied to a recommendation click. This metric justifies your machine learning infrastructure investments clearly. You must track this data across all user sessions accurately.

Measuring true incremental revenue provides clarity, as direct attribution can sometimes overlap with items users would have found via standard search. The user might have found the item via standard search anyway. You must also measure true incremental revenue. Incrementality answers a critical business question: would they have bought it anyway? True incremental revenue measures the absolute net new growth.
We use strict A/B testing protocols to measure this. We isolate a small percentage of your traffic as a holdout. A holdout group receives random items or no recommendations at all. They receive a degraded, non-personalized experience. We compare their average order value against the personalized group. The difference represents the true financial impact of your pipeline.

Our clients routinely measure significant incremental revenue gains. We ensure your reporting dashboards highlight these vital numbers clearly. You see the exact ROI of your engineering investments. The data must prove the system drives new, additive growth.

Privacy, Governance, and AI Regulation

Personalization requires user data to function effectively. However, data collection introduces significant privacy and compliance risks. Data privacy is not just a legal hurdle. It is a core component of brand trust. Shoppers remain loyal to brands that respect their personal data. We integrate strict privacy controls into your pipeline from day one. We help manage risks and ensure compliance securely. You must build your systems with strict data governance foundations.

Regulators worldwide are scrutinizing algorithmic personalization heavily. The EU AI Act demands strict algorithmic transparency. Consumers demand clear explanations for why they see specific items. The industry is moving quickly toward transparent models. Deploying explainable AI allows you to understand algorithmic decisions and maintain user trust. We design interpretable models that respect international privacy laws. We help you implement explainable AI techniques practically. These techniques map the exact features driving every single recommendation. If a user questions a suggestion, you can provide a clear reason.

You must adhere to strict GDPR data minimization principles. This means collecting only the data strictly necessary for personalization. Generating great recommendations works perfectly using just anonymous session behavior. Anonymous session behavior often provides superior predictive power. We strip personal identifiers from the data pipeline early. This protects your enterprise from catastrophic data breaches.

We align your architecture with the NIST AI Risk Management Framework. This framework ensures your models operate fairly and transparently. We audit your data supply chain to identify potential bias risks. Balancing catalog exposure ensures your algorithm represents both premium brands and affordable options fairly. This approach delights budget-conscious shoppers and protects your market share. We deploy automated monitoring tools to detect these skews early. We adjust the training data to ensure balanced catalog exposure. A compliant data machine protects your brand reputation completely. We guide your technology choices to align with long-term strategy securely.

Build vs. Buy: The Case for Custom Ownership

Retailers often debate whether to build or buy recommendation systems. The market is flooded with plug-and-play recommendation tools. These rented SaaS solutions promise instant results. They offer simple integrations and basic dashboarding. Custom ownership provides the flexibility that rented SaaS tools often restrict. Owning your pipeline allows you to tweak core logic for niche inventory and seamlessly integrate third-party data streams. In-house solutions grant full access to the underlying machine learning models.

Many engineering teams underestimate the hidden costs of SaaS tools. The initial subscription fee represents just a fraction of the total expense. You must pay massive premiums for API calls as your traffic scales. Building a custom pipeline creates valuable intellectual property and equity for your business. Rented models allow the SaaS vendor to learn from your data continuously. They use your data to improve their global model. They essentially sell your insights back to your competitors.

We advocate strongly for custom architectural ownership. Building your own pipeline provides total control over business rules. You own the code, the models, and the customer data. Building your own pipeline is an investment in intellectual property. You host the infrastructure on your own secure cloud environment. You dictate the exact business rules governing the output. This ownership turns your recommendation engine into a proprietary asset. It scales exactly according to your specific enterprise needs.

We provide the engineering expertise to build these custom solutions. We build these systems using open-source frameworks whenever possible. This prevents vendor lock-in and reduces long-term licensing fees. We ensure your in-house team understands every component thoroughly. Your engineering team gains deep institutional knowledge during the build process. They learn how to debug and optimize the model independently.

Creating in-house knowledge ensures lasting independence from external vendors. We implement AI solutions tailored to real business needs. This partnership empowers you to control your technological destiny completely. We position ourselves as technical guides throughout this transformation. We empower you to take the reins securely.

Conclusion & Next Steps

Building a robust recommendation pipeline requires strategic vision. You must combine scalable infrastructure with intelligent hybrid algorithms. Solving cold start challenges prevents lost revenue from new traffic. Tracking strict conversion metrics proves the financial value of personalization. We design and implement these powerful systems alongside your team. You gain total ownership of a revenue-generating data asset. Our goal involves empowering your enterprise to dominate your market. Contact us today to start building your custom recommendation engine.

Frequently Asked Questions

What is the best algorithm for an e-commerce recommendation system? There is no single perfect algorithm for all situations. The best approach involves hybrid recommendation engine algorithms. These combine content-based filtering for new items and collaborative filtering for popular items.

How do you solve the cold-start problem? You solve it by using contextual signals and rich product metadata. For new users, rely on session context and segmented popularity. For new products, utilize content-based embeddings and multi-armed bandit exploration.

How do recommendation engines increase average order value (AOV)? They increase AOV by predicting and displaying highly relevant cross-sell items. Suggesting complementary products right before checkout maximizes shopping cart size metrics directly.

References

  1. NIST AI Risk Management Framework: https://www.nist.gov/itl/ai-risk-management-framework
  2. GDPR Data Minimization: https://gdpr.eu/what-is-gdpr/

Article By:

https://stellans.io/wp-content/uploads/2026/01/1723232006354-1.jpg
Roman Sterjanov

Data Analyst

Related Posts

    Get a Free Data Audit

    * You can attach up to 3 files, each up to 3MB, in doc, docx, pdf, ppt, or pptx format.
    This site is protected by reCAPTCHA and the Google Privacy Policy and Terms of Service apply.