Architecting a Scalable Custom AI Image Generator Pipeline for Brands

7 minutes to read
Get free consultation

Adopting custom models trained on proprietary assets is the new standard for enterprises. Navigating this transition successfully relies on a robust data engineering backbone. A successful AI image generator requires a secure foundation tailored to your exact needs.

Custom self-hosted environments optimize your infrastructure safely and prevent the runaway API costs often caused by generic public tools. Keeping your private asset data off public networks is our priority. We build secure environments that integrate smoothly with your internal marketing tools.

At Stellans, we view image generation as a data engineering challenge. Prompts, model weights, and generated outputs are highly governed enterprise assets. We work with you to unlock data potential safely. This guide outlines how to build a governed pipeline. We will show you how to securely host an image generator AI at scale.
Core Components of a Scalable AI Image Workflow

Smooth coordination between request intake and GPU execution builds a reliable pipeline. We design well-oiled data systems that handle massive traffic spikes gracefully.

The Detailed Block Blueprint: Auto-Scaling GPU Configurations

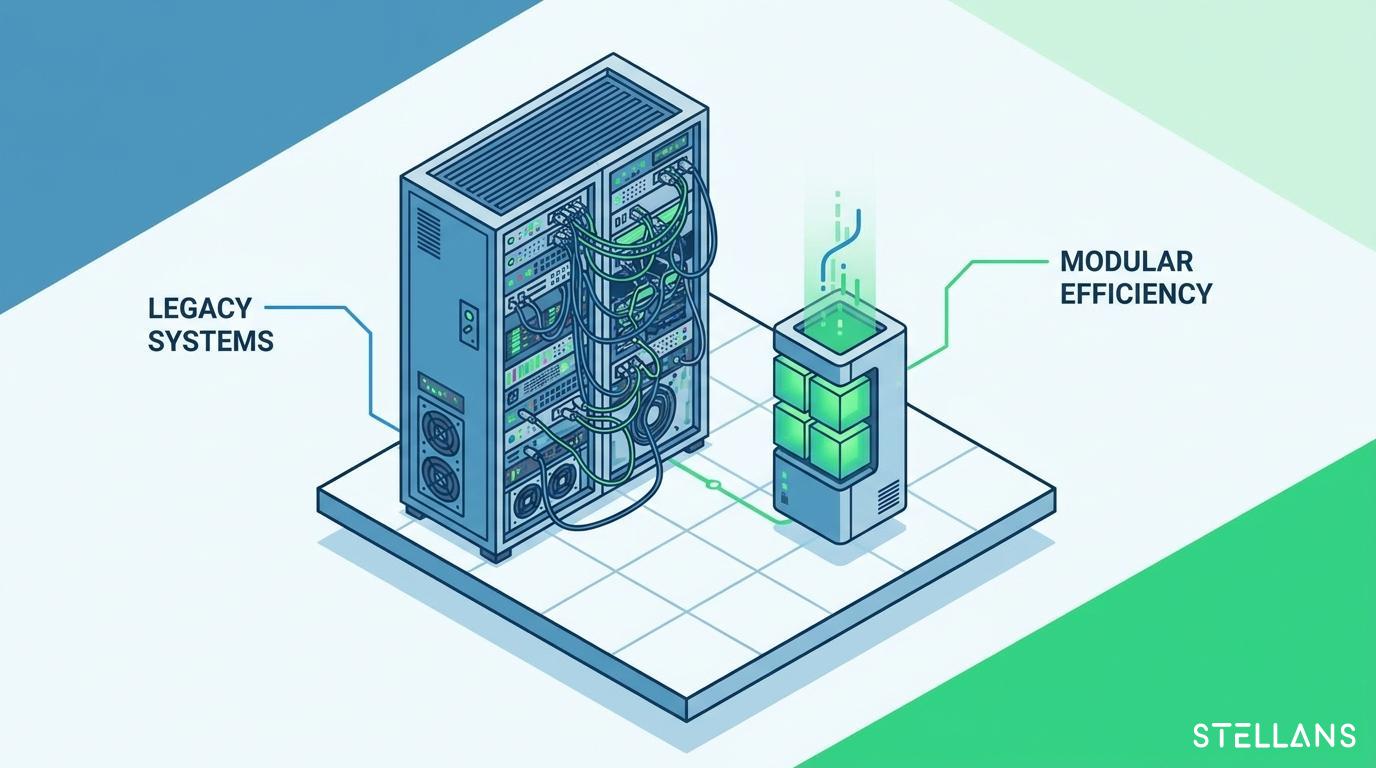
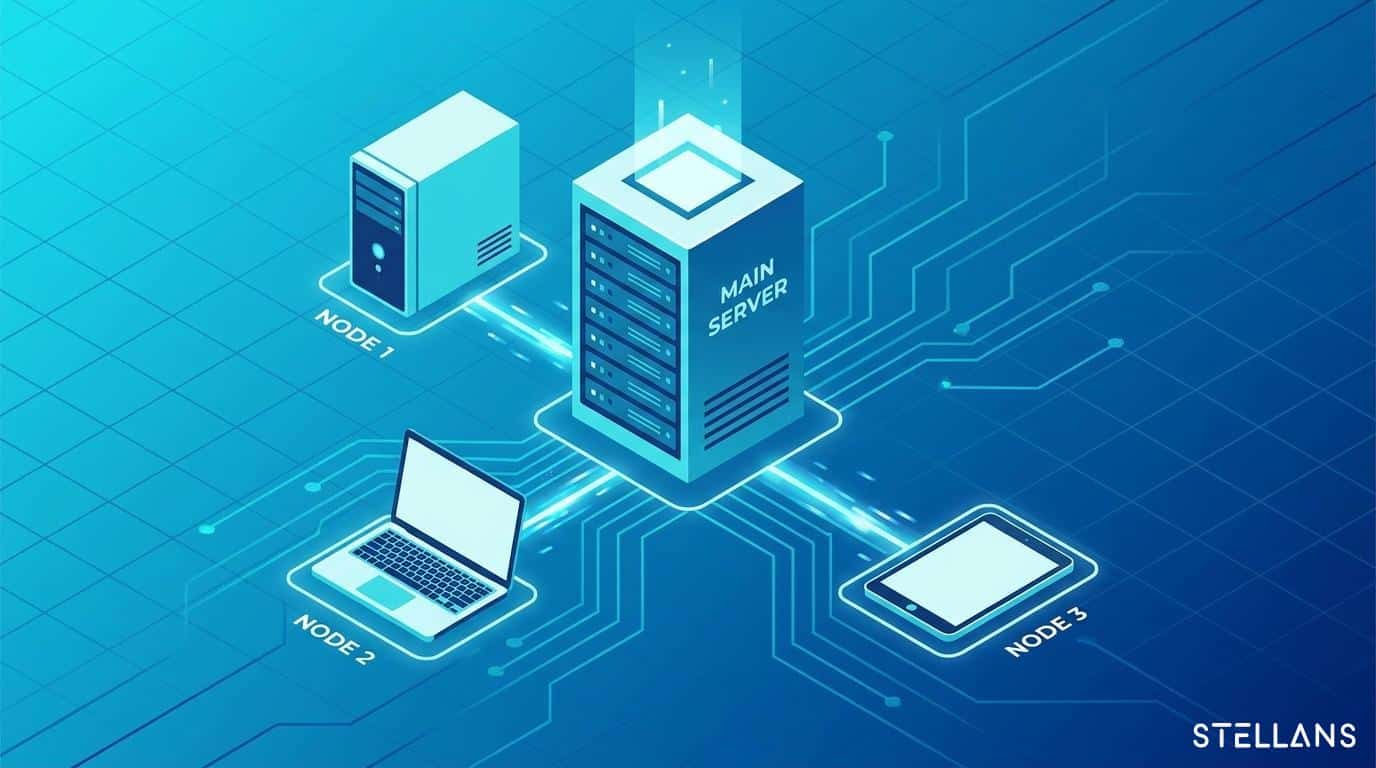
A custom AI image generator demands an intelligent architecture. The core flow starts at an API Gateway. The gateway routes incoming requests to a central Task Queue like Kafka or Redis. This queue then connects directly to auto-scaling GPU Worker Pools.

We divide these worker pools into two distinct groups. The first group handles real-time interactive requests exclusively. The second group manages large-scale batch generation tasks. Auto-scaling policies adjust cluster sizes dynamically. These policies monitor task volume demands and queue depth continuously.

The system maintains performance by automatically provisioning additional GPU nodes when the queue deepens. We configure Kafka partitions to match GPU worker node counts perfectly. Scaling down when traffic subsides saves resources. This strategy prevents compute bottlenecks efficiently and optimizes your cloud server spending significantly.

Request Intake, Prompt Construction, and Brand Constraints

Ensuring high-quality outputs starts with strict validation protocols for raw user inputs. Enriching prompts before they hit the inference layer guarantees safety and accuracy. We implement prompt engineering guardrails at the gateway level.

Our pipelines cross-reference inputs against strict brand compliance rules. We filter out prohibited terms immediately. The system then appends specific negative prompts to ensure brand safety. This guarantees that your stable diffusion integration produces accurate results.

Hosting Weights in Secure Storage for Sub-Second Target Responses

Achieving extremely low latency is essential for serving custom models effectively. We optimize storage layers to fetch model files instantly.

VPC Secure Image Pipeline Design

Maintaining enterprise security involves isolating tenant data properly. We implement IAM least-privilege principles across the board. Here are the steps to query weights under sub-second target response windows:

  1. Secure Storage Hosting: We place stable diffusion model weights inside encrypted, brand-specific buckets.
  2. Request Validation: A user request hits the API gateway for immediate validation. The system validates it against a fast prompt cache.
  3. Adapter Fetching: The system retrieves the required LoRA adapter from a warm SSD cache.
  4. GPU Loading: The adapter is loaded into a warm GPU pool instantly.
  5. Image Delivery: The GPU processes the inference and returns the final asset rapidly.

This process achieves < 1s latency easily. We use local SSD caches alongside warm GPUs. This setup prevents cold starts completely.

Real Storage Budgeting Projections for Millions of PNG Variations

Managing cloud costs effectively requires real storage budgeting projections, as generating assets at scale creates massive data footprints. Our clients regularly generate millions of PNG variations monthly.

Let us calculate the baseline storage costs together. We assume exactly 1 MB per PNG asset. Generating 5 million images requires ~5 TB of storage capacity. Implementing a rigorous tiered storage strategy ensures cost-efficiency, as storing this entire volume on high-performance SSDs is cost-prohibitive.

First, we place recent assets in Hot Storage for 90 days. This tier ensures immediate retrieval for active campaigns. Second, assets move to Warm Storage for 12 months. Finally, older assets migrate to a Cold Archive base. Archiving old assets reduces cloud storage bills drastically.

Retrieval speed relies heavily on rich metadata tagging. We catalog all EXIF and XMP data rigorously. We then ingest this metadata into Snowflake for rapid querying. This cataloging approach ensures instant asset discovery for your teams.

Solving the Top 3 Enterprise Pain Points

Custom infrastructure deployments provide relief for enterprise technology leaders seeking alternatives to generic SaaS models. We solve operational frustrations through scalable deployments.

Controlling Runaway API Costs

Custom infrastructures enable predictable budgeting by eliminating per-call SaaS fees. Our pipelines utilize optimized spot-instance GPU scaling. We also deploy aggressive caching layers at the network edge to reduce redundant generation costs significantly.

Securing Unprotected Asset Data

Keeping proprietary brand training data within a private VPC ensures it stays secure and prevents the data leakage risks of public platforms. Our teams implement tools like Satori Cyber and Snowflake. These tools provide row-level masking and complete audit trails. We help you establish strong governance foundations for your underlying technology.

Eliminating Erroneous Brand Assets

Maintaining consumer brand trust means strictly preventing non-compliant outputs. We tie stable diffusion integration strictly to rights-cleared data. Our pipelines utilize Fivetran and dbt to process approved training inputs. Fivetran ingests rights-cleared images from legacy storage seamlessly. dbt ensures error-free reporting and precise metadata alignment. This guarantees on-brand image generation consistently.

Integrating AI Image Generators with MarTech Ecosystems

Connecting your generation pipeline directly to existing marketing platforms prevents operational silos. This seamless connection creates a unified content engine for your enterprise.

Our engineers sync the pipeline with Digital Asset Management platforms. We also integrate with PIM and CMS tools effortlessly. We orchestrate these modern data engineering integrations to move data securely. This integration enables campaign orchestration without manual asset transfers.

Legal and Ethical Considerations in AI Image Generation

Ensuring asset provenance provides peace of mind and commercial safety for enterprises today. Using vetted, brand-owned training data ensures complete legal compliance.

Strict output governance protects your organization from liability. We ensure your custom AI image generator references only rights-cleared data. The pipeline logs the exact origin of every model weight. This tracking creates a defensible audit trail for your legal team.

Conclusion

Transitioning to a custom AI image generator requires strategic engineering. You must master GPU auto-scaling, secure storage, and metadata cataloging. A well-designed modern data stack makes this transformation possible.

We build scalable systems and infrastructure that fuel your enterprise growth. We streamline your infrastructure to eliminate SaaS constraints securely. Let us help you architect a compliant and governed data pipeline. Explore our comprehensive consulting services to start your transformation today.

Frequently Asked Questions

What is an AI image generation pipeline? An AI image generation pipeline is a connected infrastructure system. It manages the entire workflow from prompt intake to final image storage. It includes API gateways, GPU worker pools, and secure storage layers.

How do you scale a custom AI image generator? You scale an AI image generator by utilizing auto-scaling GPU worker pools. A central task queue monitors incoming traffic demands continuously. The system provisions new GPU nodes automatically when queue depths increase.

How much storage is needed for millions of AI-generated images? Storage requirements depend heavily on asset resolution and format. Assuming an average size of 1 MB per PNG file, 5 million images require approximately 5 TB of storage. We recommend a tiered storage strategy to manage these costs effectively.

References

Article By:

https://stellans.io/wp-content/uploads/2026/01/leadership-2.jpg
Anton Malyshev

Co-founder

Related Posts

    Get a Free Data Audit

    * You can attach up to 3 files, each up to 3MB, in doc, docx, pdf, ppt, or pptx format.
    This site is protected by reCAPTCHA and the Google Privacy Policy and Terms of Service apply.